0%

Artificial Neural Networks

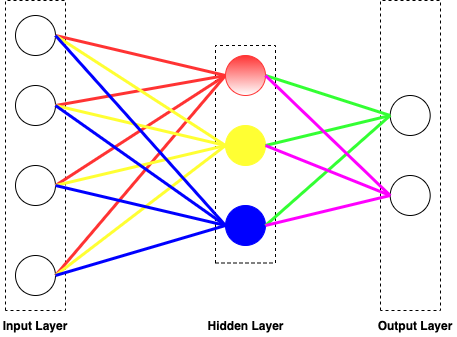
Artificial Neural Networks (ANNs) are loosely modeled after the brain. ANNs are composed of units (also called nodes) that are modeled after neurons, with weighted links interconnecting the units together.

What ANN?

Overall, the ANN contains input layer, hidden layer and the output layer.

Read more »

Matrix/vector manipulation

You should be comfortable with these rules. They will come in handy when you want to simplify an expression before differentiating

  • (AB)T=BTAT(AB)^T = B^TA^T
  • (aTBc)T=cTBTa(a^TBc)^T = c^TB^Ta
  • aTb=bTaa^Tb = b^Ta (the result is a scalar, and the transpose of a scalar is itself)
  • (A+B)C=AC+BC(A + B)C = AC + BC (multiplication is distributive)
  • (a+b)TC=aTC+bTC(a + b)^T C = a^TC + b^T C
  • AB=/ BAAB {=}\mathllap{/\,} BA (multiplication is not commutative)
Read more »

Linear Function

Let’s say we decide to approximate y as a linear function of x

hθ(x)=θ0∗x0+θ1∗x1+...+θn∗xn=∑i=0nθi∗xi=(θ0θ1...θn)T∗(x0x1...θn)h_{\theta}(x) = \theta_0 * x_0 + \theta_1 * x_1 + ... + \theta_n * x_n = \sum_{i=0}^n \theta_i * x_i = \begin{pmatrix} \theta_0 \\ \theta_1 \\ ... \\ \theta_n \end{pmatrix}^T * \begin{pmatrix} x_0 \\ x_1 \\ ... \\ \theta_n \end{pmatrix}

where the θi\theta_i’s are the parameters (also called weights) parameterizing the space of linear functions mapping from XX to YY, θ\theta and xx are both n∗1n * 1 vectors
In case of a collection of dataset xx and yy, let’s say xjx^j and yjy^j is the jthj^{th} data, the linear function can be written as

Hθ(X)=(y0y1...yn)=(θ0∗x00+θ1∗x10+...+θn∗xn0θ0∗x01+θ1∗x11+...+θn∗xn1...θ0∗x0m+θ1∗x1m+...+θn∗xnm)=(∑i=0nθi∗xi0∑i=0nθi∗xi1...∑i=0mθi∗xim)=(x00,x10,...,xn0x01,x11,...,xn1...x0m,x1m,...,xnm)∗(θ0,θ1,...,θn)T=X∗θH_{\theta}(X) = \begin{pmatrix} y_0 \\ y_1 \\ ...\\ y_n \end{pmatrix} = \begin{pmatrix} \theta_0 * x_{0}^{0} + \theta_1 * x_{1}^{0} + ... + \theta_n * x_{n}^{0} \\ \theta_0 * x_{0}^{1} + \theta_1 * x_{1}^{1} + ... + \theta_n * x_{n}^{1} \\ ... \\ \theta_0 * x_{0}^{m} + \theta_1 * x_{1}^{m} + ... + \theta_n * x_{n}^{m} \end{pmatrix} = \begin{pmatrix} \sum_{i=0}^n \theta_i * x_i^0 \\ \sum_{i=0}^n \theta_i * x_i^1 \\ ... \\ \sum_{i=0}^m \theta_i * x_i^m \end{pmatrix} = \begin{pmatrix} x_0^0, x_1^0, ..., x_n^0 \\ x_0^1, x_1^1, ..., x_n^1 \\ ... \\ x_0^m, x_1^m, ..., x_n^m \end{pmatrix} * \begin{pmatrix} \theta_0, \theta_1, ..., \theta_n \end{pmatrix} ^T = X * \theta

Read more »